AI Term of the Moment
grief tech
Redirected from: inference runtime
Definition: AI inference
The hardware and software in an AI system that does processing for the user. A peculiar name for sure; however, the inference term dates back to very early AI systems. See expert system.
A Term with Wiggle Room?
The English word "inference" implies assumption and conjecture. Apparently, in the early days of AI, "inferring" an answer seemed a safer bet than "generating" the answer, which implies a degree of accuracy. Perhaps that term will provide some wiggle room in a future lawsuit! See neural network and deep learning.
Context and Decode
To increase performance in today's AI datacenters, "disaggregated inference" executes in two stages. To analyze the question, the "context" stage requires a huge amount of computation. The "decode" stage requires fast data transfer and high-speed memory. See long-horizon context.
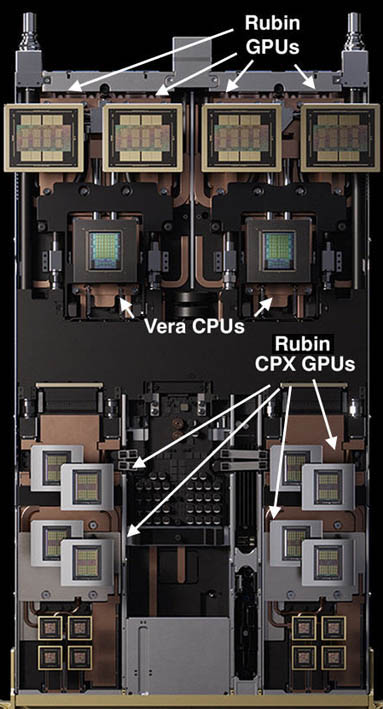
Different GPUs for Disaggregated Inference
A Term with Wiggle Room?
The English word "inference" implies assumption and conjecture. Apparently, in the early days of AI, "inferring" an answer seemed a safer bet than "generating" the answer, which implies a degree of accuracy. Perhaps that term will provide some wiggle room in a future lawsuit! See neural network and deep learning.
Context and Decode
To increase performance in today's AI datacenters, "disaggregated inference" executes in two stages. To analyze the question, the "context" stage requires a huge amount of computation. The "decode" stage requires fast data transfer and high-speed memory. See long-horizon context.
This NVIDIA Vera Rubin compute tray combines context GPUs (CPX) and Rubin GPUs. Along with switching trays, one server rack holds as many as 18 of these trays (see Vera Rubin). (Image courtesy of NVIDIA.)