AI Term of the Moment
Expressive Media Universe
Definition: AI hyperparameter
A value that directs the machine learning process and is adjusted throughout the training process. Selected by the neural network designer, hyperparameters are chosen before any training is done. Examples are the number of hidden layers in the network, the number of nodes/neurons per layer and training epochs (number of passes through the dataset). The number of training samples in the dataset and learning rate (how much the weights are changed) are also hyperparameters. See AI training vs. inference and neural network.
Parameters Are the Weights and Biases
Both hyperparameters and parameters (numeric weight and bias values) are set at the beginning of a new model, but AI engineers often change the hyperparameters. However, in the training stages, the numeric values in the parameters are continuously updated by software (see weights and biases).
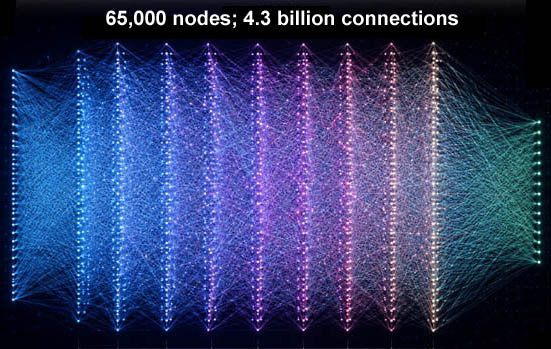
More Parameters than Neurons
Parameters Are the Weights and Biases
Both hyperparameters and parameters (numeric weight and bias values) are set at the beginning of a new model, but AI engineers often change the hyperparameters. However, in the training stages, the numeric values in the parameters are continuously updated by software (see weights and biases).
There are orders of magnitude more parameters than nodes/neurons. For example, two adjacent layers each with a thousand neurons have a million (1,000 x 1,000) weights plus 1,000 biases. This example has 65,000 neurons between input and output layers for more than four billion connections/parameters. In 2026, xAI's Grok 5 model is said to have at least six trillion parameters (see Grok AI). (Example generated by ChatGPT.)